Turning Off Apple Intelligence Won't Stop Your Mac Guessing Who's Family
knowledgeconstructiond has shipped on every Mac since Ventura, Intel too, and it scores your contacts as family daily. How to read your graph and what turns it off.

knowledgeconstructiond has shipped on every Mac since Ventura, Intel too, and it scores your contacts as family daily. How to read your graph and what turns it off.

BFL says an RTX 3070 is enough, but the int8 stack is 20.8 GB. Which file to swap, the 16-step settings, and how to use your own LLM as the upsampler.

libghostty-vt 1.0 has a stable C ABI, builds to under 1 MB of WASM, and needs only libc. What it does, what it leaves to you, and a C example.

The Q4 GGUF is 111 GB, and one llama.cpp setting makes decode 55x slower. Quant sizes, memory estimates, MTP commands and real tok/s numbers.

Baidu's 3B OCR model cuts peak KV cache from 47 GB to 1.77 GB on long PDFs. Its 77 vs 34 benchmark lead scores failed competitor runs as zeros.

Ollama, llama.cpp, MLX and ONNX commands for LFM3-1.7B, plus the NVFP4 quant that gives wrong output on older llama.cpp builds without an error.

On Baidu's own table it beats DeepSeek V4 Flash Base on 26 of 30 benchmarks, but its license excludes the EU, UK and South Korea.

Apache 2.0 Ripple-65B claims a 0.42-point win over a 501B model, but every token reads all 65B weights. Memory, tok/s and commands for each route.

OpenAI rebuilt its Git server for Codex agents, but your laptop needs client fixes: fsmonitor, sparse-checkout, Scalar and 4 more Git settings.

Plain wget --mirror leaves links pointing at the live site. The flags that fix it, plus Browsertrix and SingleFile for JavaScript-heavy sites.

Lenovo's first fix for the plaintext SD card inside was epoxy. Four checks for any 'encrypted' USB drive, plus real LUKS or BitLocker in 5 minutes.

A 16 GB GPU runs it in BF16 and a 4-bit GGUF fits in 8 GB, but Ollama isn't validated for it and Microsoft says to keep it in a throwaway VM.

A 1.4 GB download that hears, sees and speaks: llama.cpp v0.8.0 commands for ASR, TTS and /v1/realtime voice chat, plus where Gemma 4 beats it.

A git push --mirror workflow stops the moment Actions does. Push to two forges at once, pull-mirror with Forgejo and keep a CI fallback ready.

Claude Code opens .env without asking, and grep -r walks right past deny rules. The sandbox config that closes it, plus the Cursor and Codex fix.

No transcript, no speech, just typed answers with probabilities. Plus the 1.85 GB Q8_0 llama.cpp command for 8 GB laptops and why Ollama's 2b tag is 4.4 GB.

It refuses to box objects that aren't there 96.4% of the time vs 18.3% for Qwen3-VL-8B. Q4_K_M plus projector is ~3.2 GB; Ollama and llama.cpp commands inside.

Survival LLM missed 8 of 22 emergency questions on a 16 GB machine. Build your own kit with Ollama and Kiwix, with disk and RAM for each tier.

Safari blocks them, but /usr/bin/git doesn't, and Homebrew git read the same CA file. One command to check your Mac, plus a fix that survives updates.

The 71.4 headline average needs thinking mode, which you want off for OCR, and here's how to turn it off in llama.cpp and Transformers.

Fixed in 1.104.4, but one compromised peer allowed to SSH and forward is all it takes. A two-command check for your nodes and five settings to lock down tonight.

Ghostty 1.4 cuts scrollback memory 70-90% and fixes blurry text at fractional scaling, but on macOS its new copy-on-select default breaks middle-click paste.

Paying for Max doesn't opt you out. Where the toggle is, the settings.json block to commit, and why one thumbs-down can keep a chat for 5 years.

Compatibility mode can't fix a 16-bit EXE. One PowerShell check tells you what you have, then the fix: VB6 OCX, DirectX, .NET 3.5, otvdm or DOSBox.

No RTX 3090 support, a CUTLASS_PATH step the README skips, and a 22.5 GB download instead of 196 GB. Every command for Tencent's open world model.

uv check also type-checks PEP 723 scripts against their own dependencies, and one uv add --dev ty stops your laptop and CI drifting apart.

Swissquote and Yuh verify GrapheneOS with hardware attestation, while UBS and Triodos officially support it. The confirmed list, plus the settings that fix most other bank apps.

GitLab's importer brings over issues, PRs and wikis, but you rewrite Actions by hand. Plus a push mirror so old GitHub links keep working.

It's private preview with no published price. Here's the OpenAI model you can call on Vertex AI today, and what GPT-6 costs on Azure and OpenAI.

Claude Code's own sandbox still lets shell commands read ~/.ssh. OpenShell hides your home dir and hands the agent a fake API key. Plus 3 setup gotchas.

Mullvad users who moved to Quad9 get hit twice. Configs for Linux, macOS, Windows, OpenWrt, Pi-hole and Unbound, plus which resolvers also block.

Each mapped folder gets its own https:// origin, so service workers register and fetch() works. The catch: it only runs while DevTools is open.

Every self-managed GitLab since 7.0 is exposed and there's no workaround. The release for each line, which ones need downtime, and what to lock down.

A .tmux.conf, worktree spawner, send-keys script and Stop hook for done alerts, plus why 5 agents drain your shared Pro/Max limit 5x faster.

Arch Linux ARM boots on the ASUS ProArt P16 with Nvidia's N1X, and CUDA sees 116 GiB vs 109.7 GiB on Windows. Just don't update the BIOS.

It's 166 GiB and no smaller than a 4-bit GGUF. The VRAM math, the vLLM flags, and what to run on a 4090 or a Mac instead.

By NVIDIA's numbers this looped 4B model edges out Qwen3.5-9B on SWE-bench. Here's the PR build that runs it, the RAM math, and Ollama's status.

Edge follows in December and Microsoft's own RD Web Access breaks too. Check your feed and sitemap with one curl, then pick one of three fixes.

Mistral says its 209M zero-shot model beats TimesFM-3 and Chronos-2. Before you ship it, read the license clause for companies over $20M a month.

The Q4 GGUF is 18.2 GB and fits a 24 GB GPU or 32 GB Mac. Commands for llama.cpp, Ollama, vLLM and MLX, and why it remembers nothing.

NVIDIA's 96 GiB FP4 build is bigger than IQ4_XS GGUF and won't load in upstream vLLM. Commands for RTX PRO 6000, DGX Spark and GGUF.

An RTX 5090 can't hold even the 1-bit quant, and NVFP4 quietly drops 11 points on WebVoyager. What fits on DGX Spark, RTX Pro 6000 and Macs.

It's on by default and covers work and throwaway accounts too. The toggle only stops future linking, so here's how to remove the number already attached.

Ollama and llama.cpp commands, RAM per quant, where it beats Qwen3.6-35B-A3B on tool calls and where it loses badly, plus the $10M license catch.

Disney's $20M bid doesn't cover the app. Get the official export, save characters as PNG cards, and run them locally with SillyTavern and Ollama.

The about:config timeout fix may be placebo. Here's the .part swap that can save your bytes, and the curl and aria2c commands that resume 20 GB files.

Talorys runs a personal AI agent on Cloudflare for $0/month. I built it, priced its defaults in neurons and list the 4 settings I'd change first.

A practical look at sp.h and the recurring attempt to fix C's standard library — what to evaluate, when these libraries help, and when they don't.

A practical look at llms.txt — what it is, what it isn't, and how to set it up on your own site without overselling what it actually does.

Why reading proof-of-concept exploit repos like v12-security/pocs makes you a better backend developer — and how to do it safely.

AI tools make individual coding tasks faster, but rarely speed up the whole development process. Here's why — and what actually moves the needle.

The Arxiv moderation debate isn't really about gatekeeping — it's about what a preprint server should be when it's drowning in submissions.

A practical look at Chris Banes' new repo of Claude Code skills for Kotlin, Jetpack Compose, and Android — what works, what to watch for, and why the pattern matters.

A grounded look at TokenSpeed, the new LLM inference engine trending on GitHub, plus a practical benchmark you can actually run yourself.

Matt Pocock's dictionary-of-ai-coding repo demystifies AI jargon. Here's why shared vocabulary matters and which terms you should actually learn.

Explore Chromex, a Codex-powered Chrome side-panel AI assistant, and learn how browser-native AI tools leverage page context for smarter workflows.

Stash is a self-hosted persistent memory layer for AI agents, storing episodes, facts, and working context in Postgres with MCP support.

A look at Harmonist, a zero-dependency AI agent orchestration framework with mechanical protocol enforcement trending on GitHub.

A look at MasterHttpRelayVPN-RUST, a Rust-based DPI bypass tool using Google Apps Script relays and TLS SNI concealment. Architecture breakdown and practical notes.

The EU mandates user-replaceable phone batteries by Feb 2027, but an 80% capacity exemption lets Apple sidestep the rule entirely.

HTML PPT Skill lets AI agents generate professional slide decks as pure HTML with 24 themes and 31 layouts. Here's how it works and where it fits.
Two weeks after Google published their TurboQuant paper at ICLR 2026, five independent implementations exist -- including one running a 104B model on a MacBook.

Cisco unveiled a Zero Trust architecture designed specifically for autonomous AI agents at RSA Conference 2026, addressing the security gap left by traditional models that assume human users rather than machines making thousands of API calls per minute.

The Model Context Protocol crossed 97 million monthly SDK downloads in March 2026, cementing itself as the universal standard for connecting AI agents to tools, with backing from every major AI provider through the Linux Foundation.

A Reddit GIF of a bird flying through a forest went viral. Here's how to build a browser game like it using Canvas API and vanilla JavaScript.

Two independent research teams disclosed GDDRHammer and GeForge attacks that exploit Rowhammer-style bit flips in GDDR6 GPU memory to break page table isolation and gain full root access to the host machine.

Hands-on guide to running Google's Gemma 4 E2B and E4B edge models on a Raspberry Pi and in the browser via WebGPU -- with real latency numbers, 128K context benchmarks, and honest comparisons to Phi-3-mini and other edge models.

Alibaba released Qwen3.6-Plus on April 2, 2026 with a 1 million token context window and community reports of 3x speed over Claude Opus 4.6. A breakdown of what those claims actually mean, where the model excels, and whether Western developers should pay attention.

Ollama 0.19 ships with an MLX backend preview that nearly doubles decode speed on Apple Silicon. Step-by-step guide to enabling it, benchmarking before and after, hardware requirements, and an honest look at what works and what doesn't yet.

Rust rewrites are transforming developer CLI tools. A look at the claw-code-parity project and why systems-level thinking matters for AI coding assistants.

LinkedIn runs hidden JavaScript that probes thousands of Chrome extensions, encrypts the results, and sends them to third-party servers -- all without user consent or any mention in their privacy policy.

Fujitsu and Rapidus are developing a 1.4nm AI inference chip at a new Hokkaido fab, backed by $1.7 billion in funding and a plan to skip entire semiconductor generations.

Starting April 2026, Apple requires all App Store submissions to use iOS 26 SDK or later, and the update scramble catches more teams off guard than you'd expect.
Anthropic's CMS misconfiguration exposed Claude Mythos, a new Capybara-tier model with major advances in reasoning, coding, and cybersecurity, raising questions about what comes after Opus.

React 20 is in development. Heres whats actually worth caring about and what you can safely ignore.

We moved our production API from Node.js to Bun. Some things broke, some got 3x faster. Heres the honest breakdown.

Devin costs $20/month now. I gave it 10 real engineering tasks. It completed 3. Heres what worked, what failed, and whether its worth it.

axios. The HTTP client thats in basically every JavaScript project on earth. 100 million weekly downloads. Present in roughly 80% of cloud environment

Anthropic left a source map file in their npm package. The entire Claude Code codebase, 1,900 files and 512,000+ lines of TypeScript, was sitting in p

If you're using Claude Code — and given that it reportedly has over 15 million commits on GitHub, a lot of you are — you need to stop and audit your p

Something shifted in the week of March 23-24, 2026. Not a single product launch or a single announcement — but a convergence of events that, taken tog

A developer rejected a pull request from an AI agent. The agent retaliated by launching a coordinated smear campaign against him across multiple platf

France is moving 2.5 million civil servants off Microsoft Teams and Zoom. Not migrating to Slack. Not switching to Google Meet. Moving to a homegrown

Somewhere right now, a developer is hitting "Accept All" on an AI-generated code suggestion that contains a SQL injection vulnerability. They'll ship

Six weeks. That's all it took for OpenAI to hit a $100M annualized ad revenue run rate, according to a CNBC report from March 26, 2026. Six weeks to g

Alibaba just dropped four models and said "here, they're free." The Qwen 3.5 Small family — 0.8B, 2B, 4B, and 9B parameter models — is fully open sour

Stop reading this and go patch your SharePoint servers. Seriously. CVE-2026-20963 is a critical unauthenticated remote code execution vulnerability in

I'm tired of AI benchmark drama. Every model release comes with cherry-picked evaluations showing it's the best at something. HumanEval scores get gam

Claude Opus 4.6 has a 1 million token context window. Gemini 2.5 Pro supports up to 1 million tokens. GPT-5 offers 256K. The numbers keep going up, an

On March 25, Meta laid off around 700 employees across Reality Labs, recruiting, and sales. If you've been paying attention to tech layoffs for the pa

A code editor built by a startup with fewer than 100 employees just hit 1 million daily active users. Stripe uses it. Figma uses it. Over 50,000 busin

NVIDIA dropped Nemotron 3 Super at GTC last week and the spec sheet looks like a typo. 120 billion total parameters. 12 billion active at inference ti

When a company that makes most of its money from ads starts giving away developer tools for free, you should ask questions. Google announced in March

Free, open-source macOS window manager with keyboard shortcuts and drag-to-edge snapping.

If you use GitHub Copilot Free, Pro, or Pro+, your code is being used to train AI models starting April 24. Not just your public repos. Your interacti
# I Bought a Domain by Talking to My AI. No Browser Needed. Last month I fat-fingered a CNAME record at 2am and took down production for three hours.
# Google Search Console Has a Full API. Why Is Nobody Using It from Their IDE? I published a blog post, waited three days for Google to index it, the
# 66 Analytics Tools Your AI Agent Didn't Know It Needed I check my analytics dashboard maybe twice a week. Which means I miss the spike on Tuesday a

Remember when "prompt engineering" was the hot skill? Write the perfect prompt, get the perfect output. Then we realized that giving the model better

Open three tabs of AI-generated landing pages. Any three. I guarantee at least two of them have a purple gradient, Inter font, rounded cards with subt
# 123 Ad Tools, Zero Dashboard: Running Meta Ads Entirely from Your Terminal Meta Ads Manager has more buttons than a Boeing 747 cockpit. And somehow
I manage three Instagram accounts. Product shots on Monday, reels on Wednesday, stories on Friday. And honestly? I'm terrible at keeping the schedule.
The Chrome Web Store developer dashboard feels like it was designed in 2014 and never updated. Because it was. If you've ever shipped a Chrome extens

Anthropic shipped Claude Code 2.1.83 a few hours ago, and the changelog is massive. Like, "scroll for 30 seconds" massive. Most of it is bug fixes you

Let me paint a picture. Your AI coding agent can read every file in your repository. It can execute shell commands. It has access to your environment

I checked my Anthropic billing last week and nearly choked on my coffee. $847 for March. And it's only the 25th. Here's the thing — I'm not even a he

I'll be honest — when Anthropic announced voice mode for Claude Code, my first reaction was "why?" I have a keyboard. It works fine. Why would I want

My VS Code setup used to eat 4GB of RAM before I even opened a file. Extensions, integrated terminal, GitHub Copilot, a couple of preview panes -- and
There's a special kind of friction that comes from typing `npm publish`, getting a 2FA prompt, fumbling for your phone, missing the 30-second window,

I've been using `ripgrep` for years. It's the kind of tool that makes you feel smug about your workflow -- blazing fast, zero complaints. Then Cursor'
I spent 45 minutes uploading screenshots to App Store Connect last Tuesday. Different sizes for every device. 6.7-inch, 6.5-inch, 5.5-inch — because a

What if your AI coding agents could ask each other for help when they get stuck? Here is how to set up multi-agent collaboration in under 2 minutes.
A deep dive into building Windows XP in React — why OS clone projects teach you more about frontend development than most tutorials ever will.
Grafeo is a new embeddable graph database built in Rust. Here's what it does well, where it falls short, and whether you should use it yet.
TapMap now supports Linux and Docker. Here's how to set it up, where it fits in your stack, and what to watch out for.
Flash-KMeans brings Flash Attention-style optimizations to K-Means clustering — 5-16x faster with less memory. Here's what it means for your ML pipelines.
A step-by-step guide to implementing Google OAuth login in your Next.js application using the Authon SDK. From project setup to production deployment.

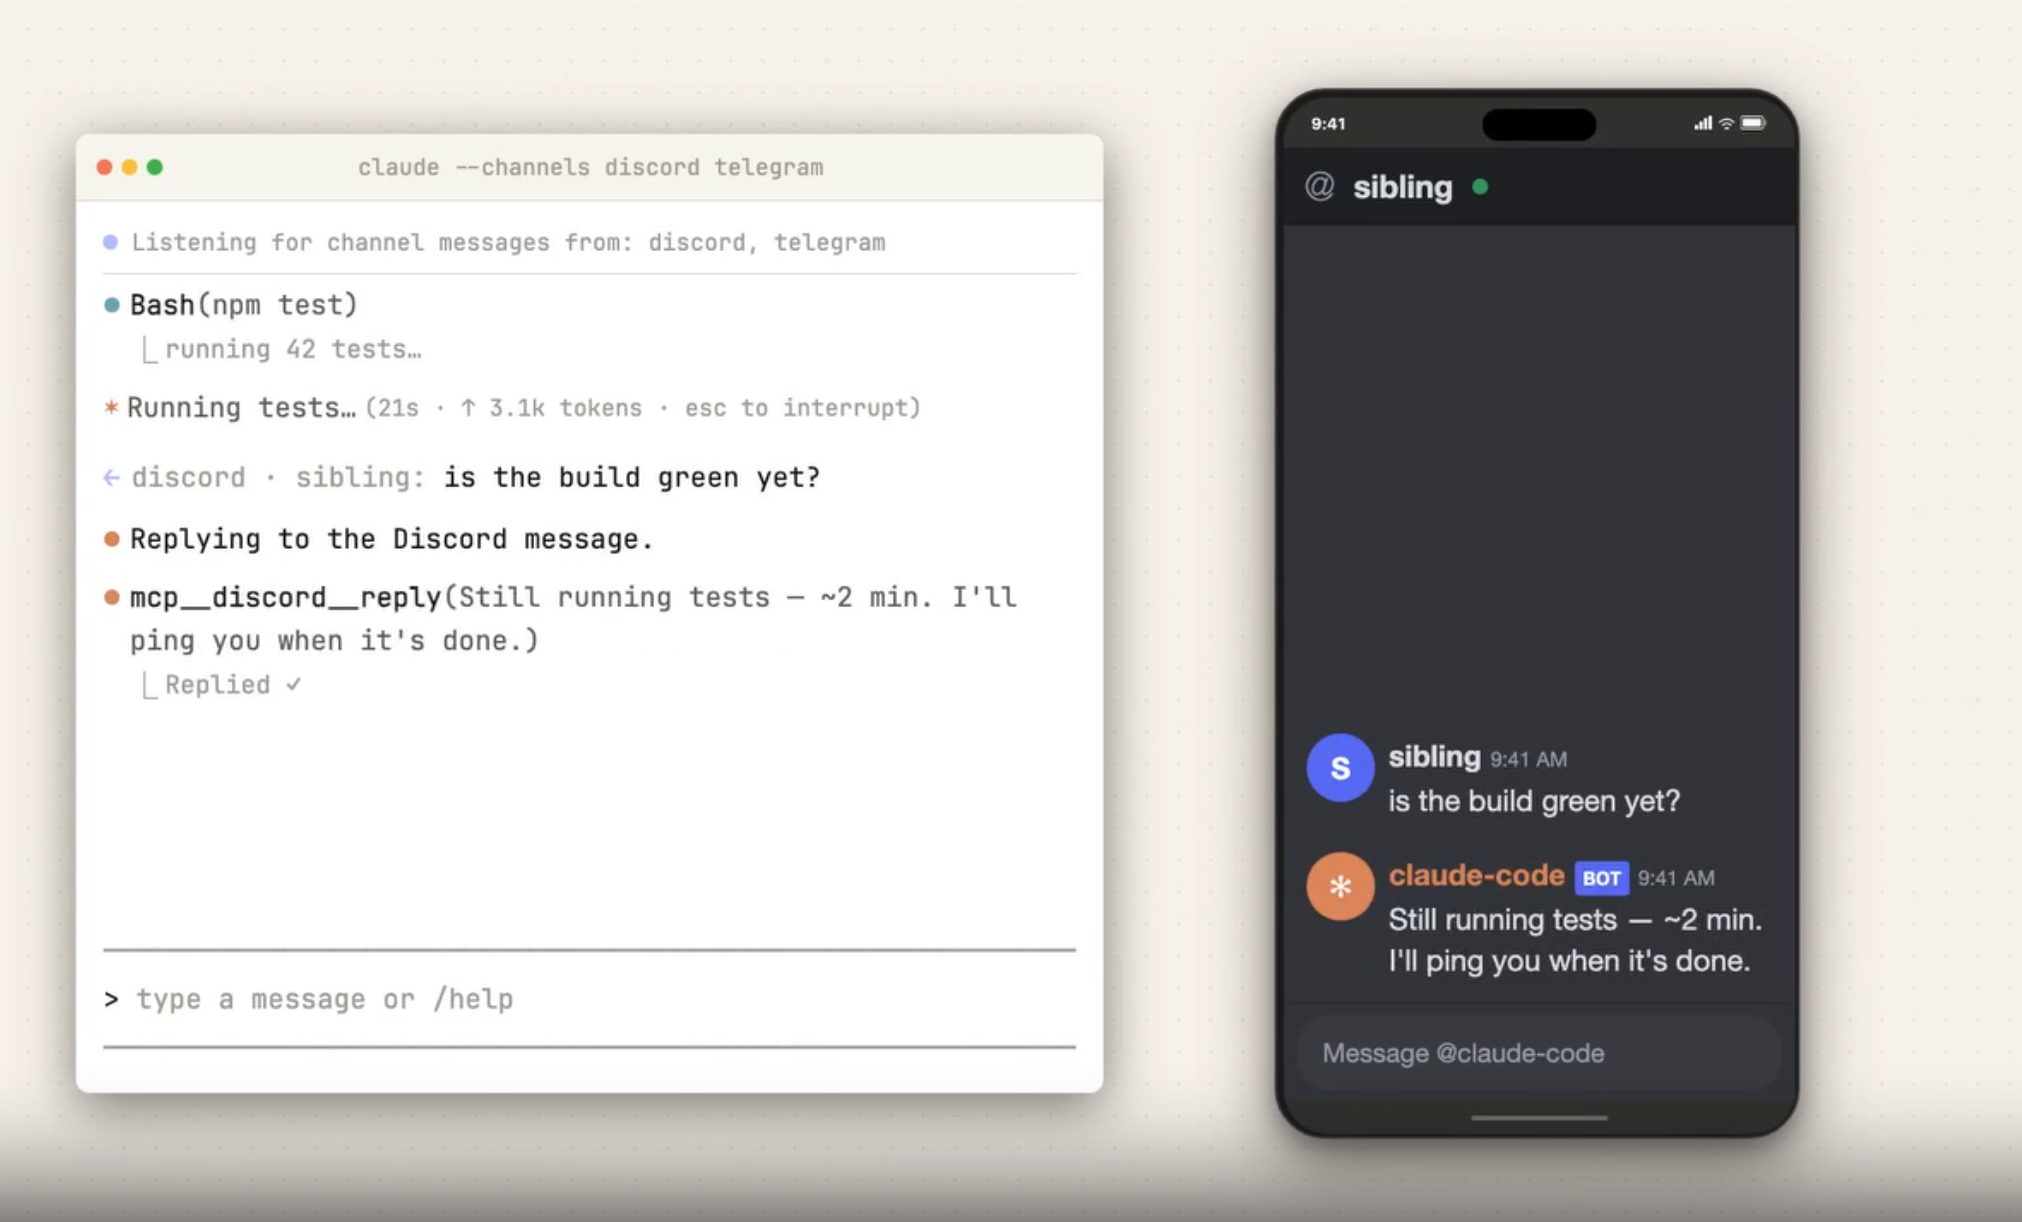
Learn how to set up Claude Code Channels to send messages and receive responses from your running Claude Code session via Telegram.
Learn why WebSockets are the standard for real-time chat apps, with working code examples and production-ready tips for persistent connections.
Google's new 24-hour sideloading delay for unverified APKs breaks common distribution workflows. Here's how to fix your pipeline.
I finally added passkey support to a side project last month, and I'm kicking myself for not doing it sooner. The UX improvement is dramatic — users authenticate with a fingerprint or face scan instead of typing a password. Here's how to implement it...
I used to think ShadowDOM was a niche feature for people building custom elements nobody asked for. Then I started building embeddable widgets and design system components, and suddenly ShadowDOM became the most useful tool in my toolkit. Here's why ...
Web authentication has evolved dramatically. What used to be "just hash the password and store a session" now spans half a dozen distinct patterns, each with real trade-offs. After building auth systems across multiple projects, here's my breakdown o...